Close
0%
0%

TaqaBuddy — a fully offline AI assistant

Handheld AI assistant that runs entirely on-device: local tool-calling, local voice, local model, local knowledge.

Similar projects worth following
147 views
TaqaBuddy is a handheld AI assistant that works without a network. Speech recognition, the language model and device control all run on a small ARM board, and nothing leaves it, because there's no radio link to send anything anywhere. You talk to it and it operates the things around you. The model's job is to pick a device and a command out of a registry it's handed at runtime. It never emits the control signal itself; ordinary code does that part. Keeping those two jobs separate is why I'm willing to let a model this small switch off something real. I'm building it on my own and writing down what happens as it happens. That includes benchmarks nobody had published, a fair number of model failures, and several occasions where the broken thing turned out to be my own test script.

Compute: Geniatech SOM-3588. Rockchip RK3588 (4× Cortex-A76 + 4× Cortex-A55, 6 TOPS NPU), 64-bit LPDDR, two MIPI DSI outputs, four I2S, 5 V input, SODIMM 314-pin at 82 × 53 mm. Sample ordered. Logs #1 and #2 cover why the first board didn't make it.

First prototype, now retired from AI work: Geniatech XPI-3566-ZERO, RK3566, 8 GB single-channel LPDDR4. It answered the question I bought it to answer, and produced the first public llama.cpp numbers for the chip while doing it.

Model: Llama-3.2-3B, Q4_0, fine-tuned with LoRA. On a 15-device registry it had never seen before, it picked the right device and command 18 times out of 19. It doesn't fabricate sensor values. What it still gets wrong is declining — it answers when it should ask. Log #3 has the numbers.

How it fits together: whisper.cpp handles speech. The fine-tuned model reads the request and the device registry, which is plain data handed to it at runtime, and names a device and a command. Ordinary code emits the actual control signal, so the model never does. GBNF grammar constraints keep the output parseable, and a check in code rejects out-of-scope requests before the model is involved at all.

Status: no demo yet. Carrier board design is the current work. The audio path that blocked the last board is straightforward on this module.
  • 1 × Geniatech SOM-3588 Rockchip RK3588 (4× A76 + 4× A55, 6 TOPS NPU), 64-bit LPDDR, 2× MIPI DSI, 4× I2S, SODIMM 314-pin. The selected compute platform — sample on order.
  • 1 × Heatsink Electronic Fitted at bring-up. Not sufficient on its own — see the benchmark log for what passive-only cooling cost.Components / Misc. Electronic Components
  • 1 × 5V USB fan Every unfanned benchmark number was thermally throttled
  • 1 × USB–serial UART adapter Console access for headless bring-up and debugging.
  • 1 × Breadboard + jumper wires Prototyping the sensor/interface modules the assistant will read from.

  • It routes 18 of 19 commands to the right device

    Adam Abu-Taqa08/23/2026 at 21:08 0 comments

    The product changed direction a couple of weeks ago. It used to be a thing that answered questions offline. Now it's a thing that operates your stuff offline: you say turn on the living room TV, and it turns on the living room TV. That makes the tool-calling work I'd been treating as a side feature into the entire product, so I went and tested it properly.

    I wrote a registry of 15 devices. Three televisions, three light groups, two locks, and a handful of other things, several of them deliberately easy to mix up. The model had never seen any of it during training. It picked the right device and the right command 18 times out of 19.

    The failures are all the same behavior. It won't say no. On ambiguous requests where it should have asked me which thing I meant, it scored 0 out of 4. On devices that weren't in the registry at all, 4 out of 7, and one of those was inventing a dishwasher. I asked it to open the blinds, which don't exist anywhere in the registry, and it dimmed the lights to zero instead. With three TVs listed I said turn off the TV and it just picked one rather than asking. That's funny with a lamp and it isn't funny with a lock, which is why it's the next thing I'm fixing.

    The other finding was my own fault. The first run scored 4 out of 30 and I almost believed it. My scorer used a non-greedy regex that stopped at the brace closing "args": {}, so every correct answer with nested JSON failed to parse and got marked wrong. Rescored properly it was 22 out of 30. That's the fourth time on this project that the broken thing turned out to be the instrument rather than the model, so I've started reading raw output before I look at any score.

    The fix is more data. I generated 4,000 training examples, and the part that does the work is that every example has a different registry in it. If they all shared one registry the model would just learn those fifteen devices. Changing it every time teaches it to read whatever list it's given, which is what I need if people are going to add their own hardware later. 2,332 of the 4,000 are cases where the correct answer is to decline or ask a question, since that's where it's weak.

    Everything I've spent on fine-tuning and evaluation so far comes to about $15 of rented GPU time.

  • The measurement that changed the hardware

    Adam Abu-Taqa08/11/2026 at 23:27 0 comments

    Big test: does more model fix the judgement problem? Ran stock and fine-tuned 1B and 3B through both evals. Capacity alone did nothing (stock 3B scored identical to stock 1B on grounded answers) and training alone did nothing, they worked together. Fine-tuned 3B took tool-calling from 5/13 to 10/13 with zero fabrications and zero inversions; the fine-tuned 1B had still said "continue to charge it" about a swollen lithium cell. The 3B produces nothing in that family.

    Unfortunately, the fine-tuned 3B on the RK3566 generates at 2.62 tok/s — below my 3.5 tok/s conversational kill line, before speech recognition contends for bandwidth. Scaling was textbook bandwidth-bound: 2.59× the parameters, 2.40× slower.

    So the compute moves to RK3588-class silicon (~10 tok/s class for 3B on the NPU per Rockchip's own tables; realistic contended estimate 5.3–6.3). The RK3566 answered the question I bought it to answer, and produced the first public numbers for the chip on the way.

  • Benchmarking a chip nobody had benchmarked

    Adam Abu-Taqa08/11/2026 at 00:37 0 comments

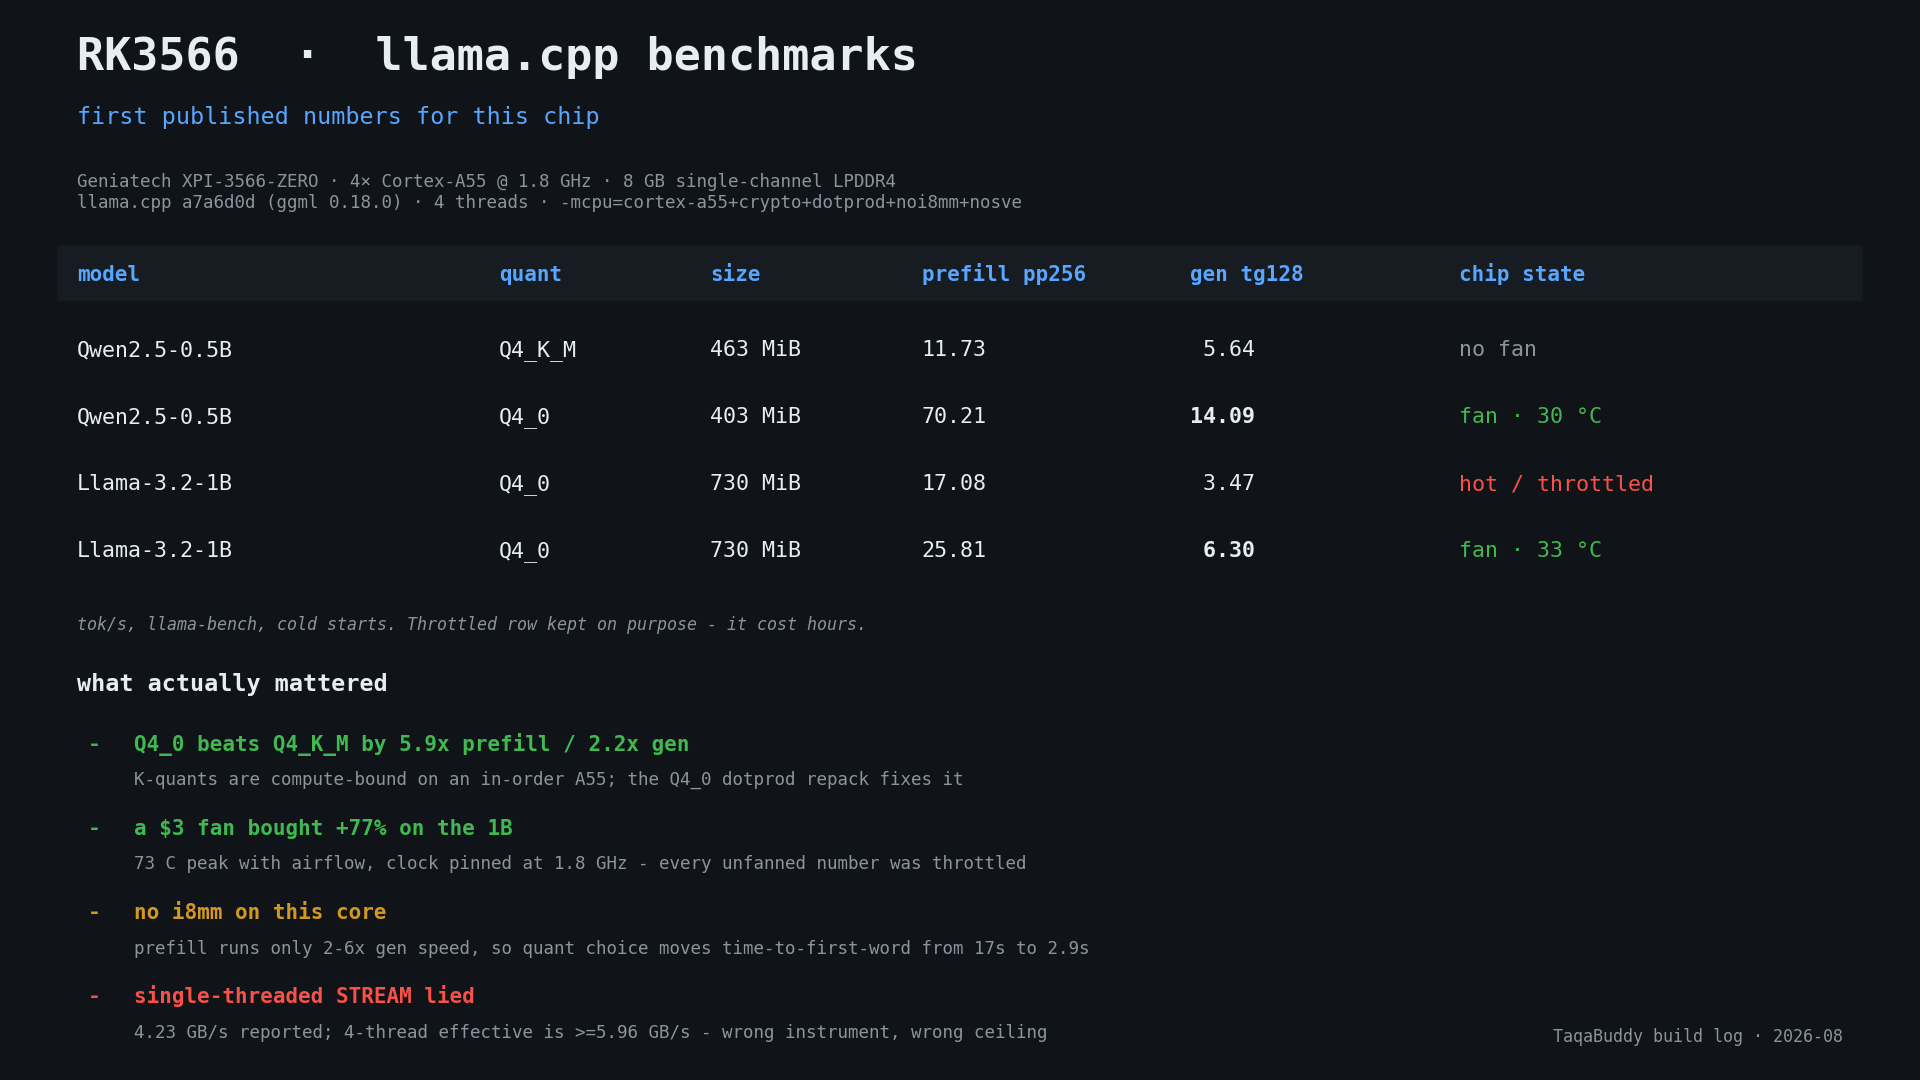
    I couldn't find a single published llama.cpp benchmark for the RK3566, so here's the first set. Geniatech XPI-3566-ZERO, 4× A55 @ 1.8 GHz, 8 GB single-channel LPDDR4, llama.cpp with cmake auto-detected -mcpu=cortex-a55+crypto+dotprod+noi8mm+nosve this core has dot-product but no i8mm, so ignore any guide telling you to add +i8mm.

    Headline numbers, 4 threads, cooled: Llama-3.2-1B Q4_0 generates at 6.30 tok/s (pp256 25.81). Qwen2.5-0.5B Q4_0: 12.31 tok/s — and note Q4_0 vs Q4_K_M matters enormously on this core (68.88 vs 11.73 prefill on the 0.5B; the Q4_0 repack path is 2–6× faster here).

    Two measurement mistakes worth confessing: a single-threaded STREAM triad understated real bandwidth (llama.cpp's four threads extract more via memory-level parallelism), and an early 1B run was silently thermally throttled. The two errors briefly agreed with each other, which looked like validation. It wasn't. Full table attached.

View all 3 project logs

Enjoy this project?

Share

Discussions

Similar Projects

Does this project spark your interest?

Become a member to follow this project and never miss any updates