Close
0%
0%

MacMind: A Transformer Trained in HyperCard

A 1,216-parameter transformer written entirely in HyperTalk, trained overnight on a Macintosh SE/30.

Similar projects worth following
MacMind is a single-layer, single-head transformer implemented entirely in HyperTalk. Embeddings, positional encoding, scaled dot-product self-attention, a residual connection, cross-entropy loss, full backpropagation, and SGD. 1,216 parameters. No feed-forward block or layer norm (at this scale, attention and a residual are enough). It runs in HyperCard 2.1 on a Macintosh SE/30 under System 7.6.1, on any 68000 Mac from System 7 through Mac OS 9, in Basilisk II or Mini vMac, and in the browser at hcsimulator.com. The training task is the bit-reversal permutation, the first step of the Fast Fourier Transform. The model doesn't know the rule. After training, the attention map shows the butterfly pattern Cooley and Tukey published in 1965. A 16 MHz 68030 rediscovers the FFT through gradient descent. 1,216 parameters here, roughly a trillion in GPT-4. The math is identical. Option-click any button and read it. Source, stacks, and a NumPy reference: github.com/SeanFDZ/macmin

MacMind is a single-layer, single-head transformer implemented entirely in HyperTalk.  It has token embeddings, positional encoding, scaled dot-product self-attention, a residual connection, cross-entropy loss, full back propagation, and stochastic gradient descent.  There are 1,216 parameters across six weight matrices.  There is no feed-forward block or layer norm, because at this scale attention and a residual are enough.

It runs in HyperCard 2.1.  The reference machine is a Macintosh SE/30 under System 7.6.1.  It should run on any 68000 Mac from System 7 through Mac OS 9, and in Basilisk II, SheepShaver, or Mini vMac.  It also runs in the browser at hcsimulator.com.

The training task is the bit-reversal permutation, the opening step of the Fast Fourier Transform (FFT).  The model doesn't know the rule.  It learns from random examples.  After training, the attention map shows the butterfly routing pattern Cooley and Tukey published in 1965.  A 16 MHz 68030 rediscovers the structure of the FFT through gradient descent.

The process that trained MacMind is the same process that trained every large language model: forward pass, loss, backward pass, weight update, repeat.  MacMind has 1,216 parameters.  GPT-4 has roughly a trillion. The math is the same, only the scale is different.

That is the point of this project, to see if the mathematics of AI that are shaping the world around us are knowable.  In HyperCard you can option-click any button and read the actual math.  It's HyperCard and HyperTalk, so there's no compiled code, external libraries.

The build logs cover the rest:  matrix math in a language with no arrays, backprop derived by hand, a 32KB script editor limit, and Apple's SANE doing every multiply in 80-bit extended precision.

Source, pre-trained stack, blank trainable stack, and a Python/NumPy reference implementation are availble for download: github.com/SeanFDZ/macmind (MIT).
MacMind-Trained.img

Pre-trained stack (1,000 steps, converged). Open in any Mac emulator with HyperCard 2.x, go to Card 3, click New Random then Permute to see it work.

x-apple-diskimage - 1.41 MB - 08/26/2026 at 17:23

Download

MacMind-Blank.img

Initialized but untrained stack. Open it, go to Card 2, and begin training it yourself.

x-apple-diskimage - 1.41 MB - 08/26/2026 at 17:22

Download

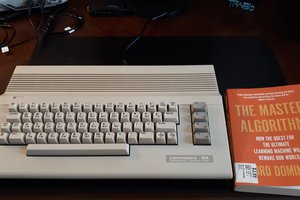
  • 1 × Macintosh SE/30 16 MHz 68030, 4 MB RAM. The training hardware.
  • 1 × HyperCard 2.1 Full authoring environment. 2.0 or later required (HyperCard 1.x lacks standard operator precedence)
  • 1 × System 7.6.1 OS on the reference machine. Anything from System 7 through Mac OS 9 should work.

  • The browser port I didn't write

    Sean09/02/2026 at 17:33 0 comments

    Shortly after MacMind went public, someone imported the stack into HyperCard Simulator at hcsimulator.com, a reimplementation of HyperCard that runs in the browser.  I had nothing to do with it, but it's my favorite thing that has happened to the project.

    The simulator does not emulate a 68030.  It reimplements HyperTalk itself in JavaScript, which changes the performance story completely.  Inside a real Mac SE/30 or even in SheepShaver running on modern hardware, training steps crawl, because the bottleneck is HyperCard's interpreter, faithfully emulated in SheepSaver at full slowness.  The simulator's interpreter runs at browser speed, and training steps that take tens of seconds under emulation finish in a couple of seconds.  You can train the model from scratch over a coffee.

    It also closes the last gap in the demystification pitch.  Until this existed, "run it yourself" meant a real classic Mac or an emulator setup, and an emulator setup both of which may filter out most of the curious.  Now the path is: open a URL, click Train 10, watch a transformer learn.  The scripts are still right there, still readable, still the same HyperTalk that runs on the SE/30.  The floor for taking apart a neural network and learning how it works is now a browser tab.

    There is something fitting about the direction of travel.  The usual retrocomputing story is old software rescued onto new platforms as a preservation act.  This is a neural network written for 1991 software, ported forward to 2026 by a friendly stranger, without a line of it changing.  

    HyperTalk didn't know what a transformer was any more than I did before I started this project. The goal was to build the engine at home and watch it work.  Now the same stack that trains on a floppy also trains in Chrome.  Isn't it time you took it for a spin?

  • The NumPy cross-check

    Sean09/02/2026 at 17:26 0 comments

    The repo includes validate.py, the identical architecture in NumPy. It uses the same six matrices, parameter count of 1,216, Xavier initialization, and learning rate of 0.01 on the same task.

    It exists to answer two questions:

    1. Does this architecture learn this task at all, independent of HyperTalk?  It does: 100 percent accuracy well before step 3,000, with a check that loss decreases on a rolling 100-step average.  Any architecture-level mistake, a wrong gradient, a missing accumulation, breaks that convergence in NumPy just as it would on the Mac.
    2. Does the HyperTalk match the math?  For that, the validator prints test vectors: a fixed input with seed 42, then row dumps of the embedded input, the query vectors, the attention weights, and the output probabilities, plus predicted digits and per-position confidence.  Every one of those has a corresponding hidden field in the stack.  Open HyperCard's Message Box, ask for act_attn or act_probs, and compare numbers against the printout.  In HyperCard, the stack is its own debugger and the fields are the tensors.

    The two implementations won't match digit for digit.  Different random draws and different arithmetic: NumPy computes in 64-bit doubles, while SANE uses 80-bit extended.  But the shapes, the convergence, the learned permutation, and the butterfly in the attention weights match.

    pip install numpy, python3 validate.py, and you have run the ground truth.  Then run the stack and watch the same math happen slowly.  Very slowly :)

  • The butterfly

    Sean09/01/2026 at 20:19 0 comments

    The bit-reversal permutation has a structure where positions 0, 2, 5, and 7 map to themselves, positions 1 and 4 swap and positions 3 and 6 swap.  Cooley and Tukey published the routing diagram in 1965, and every FFT implementation since has drawn some version of it.  The crossing pattern gave it its name: the butterfly.

    Card 4 of the stack draws an 8x8 grid, one cell per attention weight: which input position the model looks at when producing each output position.  Before training, the grid is mush.  Attention spreads roughly evenly because the weights are random.

    After the overnight run, the grid shows four strong cells on the diagonal, at rows 0, 2, 5, and 7.  The fixed points attend to themselves.  Rows 1 and 4 light up off-diagonal, each attending to the other. Rows 3 and 6, the same.  Eight bright cells, and their positions are the butterfly.

    The training loop doesn't contain the permutation, and the bitReversal handler that generates the targets is eight lines of item shuffling the model never sees.  The permutation structure was recovered from data by gradient descent, and it surfaced in the one place a single attention layer could put it: the attention weights became the routing table.

    This is why the task was chosen.  Another problem would converge and tell you nothing but a loss number.  This one converges to a diagram that easy to visualize in your mind and compare with the screen.  When the grid matches the diagram, you can compare the results yourself.  Click Refresh on Card 4 and check it against the literature.

  • 80-bit floats on a 68030

    Sean09/01/2026 at 16:57 0 comments

    The SE/30 trains this model with more numerical precision than your GPU does.

    HyperTalk arithmetic goes through SANE, Apple's Standard Apple Numerics Environment, which computes in 80-bit extended precision: a 64-bit significand, roughly 19 decimal digits.  A modern GPU training a large model uses 32-bit floats at best, about 7 decimal digits, and more commonly 16-bit formats that hold 3.  Every multiply-accumulate in MacMind's triple loops carries more digits than the hardware that trained GPT-4.

    The softmax subtracts the row maximum before exponentiating, the standard stability trick, because exp() of a large score overflows in any precision.  And exp() and ln() are the two transcendental functions the model needs: exp for both softmaxes, ln for the cross-entropy loss.  HyperTalk has both built in.  The language designed for birthday card and address book stacks shipped with everything a transformer needs.

    The real cost is speed.  HyperTalk is interpreted, so every multiply, field access, variable lookup goes through the interpreter.  The math-heavy training loop runs somewhere in the range of a hundred to five hundred times slower than compiled C.  Stack that on an interpreter running on a 16 MHz 68030 and a single training step takes several seconds.

    So the trade the SE/30 offers is exact: unlimited patience, surplus precision, but no speed whatsoever.  It's the mirror image of modern ML hardware, which trades precision away for throughput.  But both ends of the trade run the same equations.

  • Backprop by hand

    Sean08/31/2026 at 11:31 0 comments

    The gradients in MacMind were derived on paper, written into a reference document, and translated into HyperTalk.  The easy start: cross-entropy through the output softmax collapses to probs minus one-hot.  Copy the probabilities, subtract 1 at the target digit, done.  From there it's matrix calculus all the way down, and matrix calculus needs transposes, so the stack has three multiply handlers:  matMul for A x B, matMulTA for A-transpose x B, matMulTB for A x B-transpose.

    The softmax Jacobian is an 8x8 matrix per row, but it collapses: for each row, the gradient is a[i] * (g[i] - dot(a, g)), where a is the attention row and g is the incoming gradient, then divide by 4, the same 1/sqrt(16) scale from the forward pass. That formula runs in a doubly nested repeat loop over hidden fields in a single HyperCard card.

    The embedded input feeds four paths:  the residual connection, and the V, Q, and K projections.  Its gradient is the sum of all four, accumulated with an addFields handler.  The token embedding gradient is sparse: positions sharing a digit accumulate into the same embedding row.

    Weights initialize Xavier-uniform, limit sqrt(6 / (fan_in + fan_out)).  HyperTalk's random(n) returns integers, so uniform floats are (random(20001) - 10001) / 10000 times the limit.  Updates are plain SGD at learning rate 0.01, read from a visible field on the training card. Change the number, change the training.  And that is the whole optimizer.

  • Matrix math in a language without arrays

    Sean08/27/2026 at 13:13 0 comments

    HyperTalk has no arrays. It has strings, and it has item, which splits a string on commas.  That's the entire data structure inventory.  So every matrix in MacMind is a comma-delimited string in a hidden field.  A 16x16 weight matrix is 256 comma-separated numbers in a single field, row-major.  Element at row r, column c:

    get item (r * 16 + c + 1) of field "W_Q"

    Six weight fields hold the model: W_embed, W_pos, W_Q, W_K, W_V, W_out.  Nine more hold activations from the forward pass, because backprop needs them later.  Gradient fields mirror the weights with a grad_ prefix.  Card 2 of the interface carries 47 fields, 32 of them hidden, parked in a 10-pixel rectangle just below the visible card area.  The card is 512 x 342.  The model lives at y=330.

    Item lookup is O(n).  HyperTalk finds item 256 by counting 255 commas from the start of the string, every single time.  The matrix multiply does this three times per multiply-accumulate.  This isn't fast :)  for 1,216 parameters it's workable.

    Even writing zeros is expensive.  The zeroField handler builds "0,0,0,..." by string concatenation, which is O(n squared). On OS 7 that adds several seconds per call.

    What you get in exchange is something no PyTorch checkpoint offers.  The weights are text, in fields, in the stack file.  Save the stack, quit, reopen it:  the trained model is still there.  The stack file is the source code, the runtime, and the checkpoint.  If you copy the file, you have cloned the model.  The entire difference between MacMind-Blank.img and MacMind-Trained.img is 1,216 numbers.

  • Why train a transformer on a Mac SE/30?

    Sean08/26/2026 at 17:30 0 comments

    AI affects all of us.  Almost nobody understands what it does.  The usual explanation hides behind scale:  trillions of parameters, GPU clusters, training runs priced like infrastructure.  The scale can make it feel like magic.  I wanted to see if I could understand the math behind what's really happening, to strip the scale away and see that's what's left is arithmetic, arranged carefully, repeated many times.

    The test.  Take the transformer from "Attention Is All You Need" (Vaswani et al., 2017).  Shrink it to one layer and one head.  Implement it in the least plausible environment I own:  HyperCard 2.1 on a Macintosh SE/30, in HyperTalk, a scripting language from 1987 designed for making interactive card stacks.  Interpreted.  No arrays.  If the math is real, if I can understand it, then it should work on the machine I had in college.

    The architecture is 1,216 parameters across six weight matrices.  A 10x16 token embedding, an 8x16 position embedding, 16x16 query, key, and value projections, and a 16x10 output projection.  Attention scores are scaled by 1/sqrt(16), softmaxed per row, applied to the values, and added back through a residual connection.  Cross-entropy loss, gradients backpropagated through every layer including the softmax Jacobian, weights updated by plain SGD.  There is no feed-forward block or layer norm. At 1,216 parameters, attention and a residual are enough for this task. Everything that remains is the standard recipe.

    The training task is the bit-reversal permutation.  Given eight digits, output them with each position index bit-reversed:  position 001 goes to 100, position 011 goes to 110.  It's the first step of the Fast Fourier Transform.  I chose this for two reasons: it's small enough for 1,216 parameters to learn, and it has a known internal structure.  If the model learns it, the attention weights have to converge to the FFT butterfly diagram.  That gives you something rare: a way to check a neural network's homework against a 1965 paper on the screen of a 1987 computer.

    The model know any of this.  It saw random examples, one at a time, several seconds per step, all night.  By morning it had learned the permutation, and the attention map showed the butterfly.

    Next log:  storing six weight matrices in a language with no arrays.

View all 7 project logs

Enjoy this project?

Share

Discussions

Similar Projects

Does this project spark your interest?

Become a member to follow this project and never miss any updates